How to prepare your business data for AI
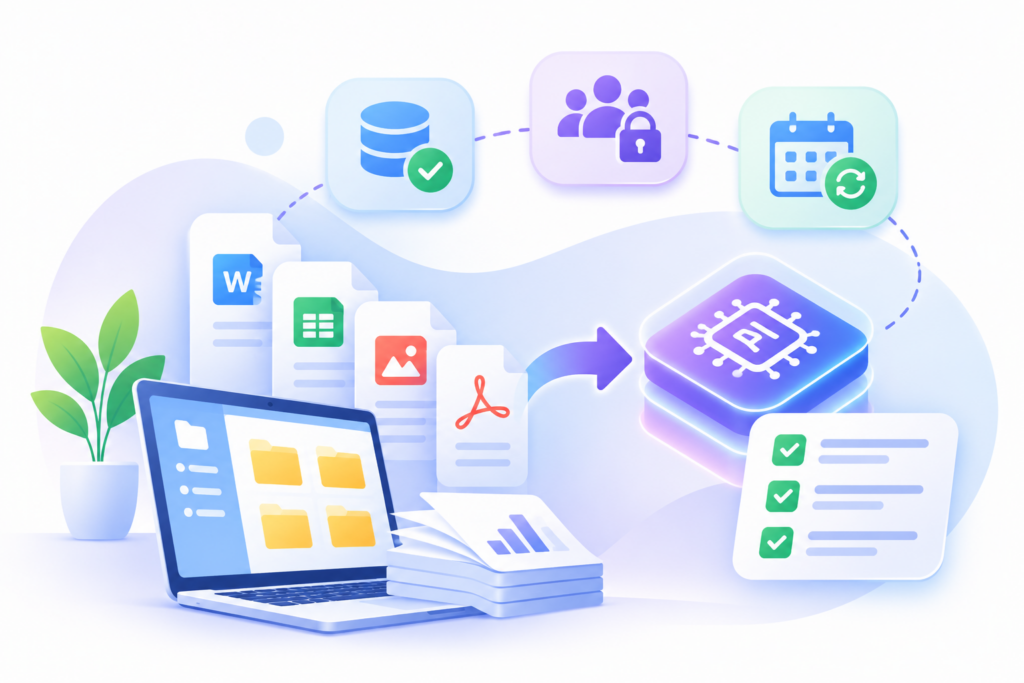
An AI assistant may answer from an obsolete policy despite a large uploaded library. Changing models may not help when sources conflict, omit information or fall outside the user’s permissions. Preparation starts with the task and approved sources.
The hypothetical example is a leave-policy assistant that neither approves requests nor needs all personnel records. It illustrates source selection, ownership and checking, not Fenix policy or project results.
1. Choose the task before collecting data
Specify the questions, expected output and who will act on it. Leave guidance needs the procedure, applicability and contact details. General guidance does not itself justify including payroll or medical records.
Different applications need different data. Search assistants need retrievable, applicable sources; invoice extraction needs sample documents and expected values; transaction forecasting needs consistent fields and outcomes. Collecting every file first is not a substitute for defining the task.
Inventory sources with owners, applicability, approval status and location. Separate usable, incomplete and excluded sources. If only part of the task has suitable data, restrict the trial to that part rather than broaden access merely to obtain more input.
2. Confirm that sources are correct and sufficient
Readable files are not necessarily correct sources. A clear PDF containing an expired policy can produce a wrong answer. Content owners must identify current and historical versions and resolve conflicts.
For example, policies for staff in Vietnam and Japan may have different applicability. One HR folder does not tell the tool which to use. Record scope and test ambiguous questions. Where applicability is unclear, seek clarification or escalate rather than let AI choose company policy.
Find omissions too. A policy stating entitlement but not submission steps cannot support a complete procedural answer. Map realistic questions to their sources and identify unanswered parts before evaluating the tool.
For tables, check headings, footnotes and page continuations. A split row can attach one group’s conditions to another even when individual words are read correctly. Test the tool’s actual processing, not just human readability of the original.
For scans and field extraction, check how text and tables are processed. How to check AI document extraction results explains comparison with originals, so a correct source does not become incorrect structured data.
3. Preserve access boundaries in the AI tool
Access to a general policy does not grant access to another employee’s private leave record. Enforce boundaries during retrieval and response. An instruction not to disclose data does not replace implemented authorization checks.
Test different user groups, including out-of-scope requests. Check available sources and whether answers summarize restricted content. Use authorized tests and suitable data, not unnecessary exposure of real records to demonstrate a flaw.
Before connecting the library, define who may view, download and manage each source group. How to assign the right user permissions helps translate business boundaries into permissions the implementation team can test.
Check the actual service’s data destination, retention, access and deletion or exit arrangements. Do not assume all providers do—or do not—use customer data for training. Verify the specific service, settings and agreement.
4. Prepare updates and evaluation data
Owners need to know when changes reach the sources the AI actually uses. Editing a local file does not update a search index automatically. On withdrawal or access revocation, check processed copies and caches where used, not just the original file.
Prepare business-approved answers for clear, incomplete, conflicting and out-of-scope cases. Reserve unseen cases for evaluation. Rechecking only examples just used to tune the tool does not establish performance on new situations.
Conclude which sources are ready, which must wait and who resolves the gaps. A verified subset can support a limited trial while other sources are improved. Carry the limits into usage and reporting rather than declaring the whole business ready.
With data scope established, evaluate whether the tool produces useful, controlled business results. When is your AI pilot ready for everyday use? explains evidence for continuing, revising and retesting, or stopping.
Start a discussion with Fenix from a small task and an authorized document set. First identify reliable sources, ownership and gaps rather than sharing the entire company library.